How Our AI Detector Works: A Transparent Breakdown of Linguistic Signals, Probabilities, and Detection Modes

How Our AI Detector Works: A Transparent Breakdown of Linguistic Signals, Probabilities, and Detection Modes
AI detectors should never operate like unexplained accusation machines. Users deserve to understand what a score represents, what influenced it, and where uncertainty remains.
AIDetector.cx examines patterns within submitted text. It estimates whether those patterns resemble human writing, AI generation, or a mixture of both.
The system does not recover a hidden authorship label from the document. No ordinary text contains a universally reliable marker proving who wrote it.
Instead, our detector evaluates several linguistic and statistical signals. It combines their evidence, measures agreement, and returns calibrated probabilities with a confidence level.
This article explains that process without presenting detection as certainty. It also shows how Balanced and Aggressive Detection serve different review needs.
What Question Does an AI Detector Answer?
Our detector answers a limited question: how closely does this text resemble patterns associated with human, AI-generated, or mixed writing?
That question differs from asking whether someone cheated, violated a policy, or used an AI tool improperly. Software cannot determine those circumstances from wording alone.
The detector also does not perform plagiarism checking. Plagiarism analysis searches for meaningful similarities between submitted text and existing sources.
AI detection examines linguistic origin signals within the text itself. A passage can be original yet AI-generated, or human-written yet copied from another source.
Keeping these questions separate prevents misleading conclusions. It also helps teachers, editors, students, and researchers choose the correct tool for each review.
The Detection Process at a Glance
The analysis begins when a user submits text. The system validates the input, identifies its likely language, and prepares it for sentence-level examination.
Preprocessing separates meaningful language from formatting noise. It standardizes distracting elements while preserving wording, punctuation, structure, and contextual relationships.
The detector then measures several signal families. These include predictability, sentence variation, vocabulary distribution, syntactic regularity, repetition, cohesion, and local style changes.
No single signal decides the result. The system combines evidence because every individual feature can also appear in legitimate human writing.
Language-aware calibration adjusts how the combined evidence is interpreted. The interface then presents AI, HUMAN, and MIXED probabilities, confidence, and detected language.
Signal One: Word-Choice Predictability
Language models generate text by estimating likely continuations from preceding context. Their outputs can therefore favor words and phrases that fit statistically expected patterns.
Our detector examines how predictable word choices appear across a passage. Repeatedly safe and contextually obvious selections can contribute AI-like evidence.
Predictability does not prove AI authorship. Clear instructions, legal language, technical definitions, and non-native English can also contain highly expected wording.
Research supports examining probability patterns, although different detectors use different methods. The DetectGPT study identified measurable probability-space differences in machine-generated passages.
AIDetector.cx does not treat that research method as a universal authorship test. Predictability remains one component within a broader evidence model.
Signal Two: Sentence Variation and Burstiness
Human writing often changes pace. A writer may use a short statement, develop a detailed explanation, and then return to a concise conclusion.
This variation is sometimes called burstiness. It can involve sentence length, clause density, punctuation, rhythm, and structural complexity.
AI-generated passages may show unusually even pacing across many sentences. They can repeat similar lengths, grammatical shapes, and paragraph-development patterns.
However, low variation is not automatically suspicious. Academic abstracts, policy documents, product descriptions, and carefully edited articles may follow consistent structures.
Our system measures variation without requiring writers to sound irregular. It considers burstiness alongside topic, language, document length, and other signals.
Signal Three: Syntax and Grammatical Regularity
Syntax describes how words and phrases form sentences. The detector examines recurring sentence frames, clause arrangements, agreement patterns, and grammatical consistency.
Some machine-generated text maintains near-perfect regularity for long stretches. It may repeatedly introduce claims, explain them, and conclude them using similar constructions.
Human prose often contains more personal habits and local irregularities. These can include fragments, interruptions, unusual emphasis, or inconsistent sentence development.
None of those features makes writing better or more human. Professional editing can remove irregularities, while AI systems can deliberately imitate them.
For that reason, syntactic regularity adds weight only when related evidence supports the same interpretation.
Signal Four: Vocabulary Distribution and Repetition
The detector evaluates how vocabulary is distributed throughout a passage. It looks beyond repeated words and considers repeated functions, phrases, and semantic patterns.
Machine-generated writing may reuse polished transitions, balanced phrases, or abstract nouns at unusual frequencies. It may also restate one idea without adding evidence.
Human writers repeat language too, especially within technical subjects requiring stable terminology. Repetition becomes informative only when its pattern appears unusually systematic.
Vocabulary diversity also requires context. A narrow subject naturally limits word choice, while creative writing may use broader and less predictable language.
The system weighs repetition against passage length, topic consistency, language, and surrounding sentence behavior. It does not reward unnecessary synonyms or complicated vocabulary.
Signal Five: Cohesion and Transition Patterns
Cohesion describes how sentences and paragraphs connect. Strong writing should maintain understandable relationships between claims, evidence, examples, and conclusions.
AI-generated content can sound smooth while following highly reusable transition patterns. Each paragraph may connect correctly, yet the progression can feel mechanically balanced.
Other generated passages contain abrupt logical jumps hidden behind fluent wording. Their transitions sound convincing, although the underlying claims remain weak or unsupported.
Our detector examines local and document-level connections. It measures whether transitions, topic development, and semantic relationships appear naturally varied or unusually templated.
Smoothness alone never triggers an AI verdict. Clear human writing should not be penalized merely because it is organized and readable.
Signal Six: Sentence-Level Changes
Entire documents rarely have one perfectly consistent origin. People may revise AI drafts, quote sources, receive editorial help, or combine several contributors’ work.
Sentence-level analysis helps identify local changes that document-wide averages may conceal. These changes can involve vocabulary, rhythm, predictability, syntax, or tone.
A sharp shift does not prove AI use. A quotation, technical definition, translated section, or later revision can produce the same effect.
Flagged passages should therefore guide closer reading. They show where the evidence changed, not where misconduct definitely occurred.
This distinction is essential for mixed-authorship documents. A single overall percentage cannot explain every sentence or every stage of the writing process.
How We Combine Multiple Signals
After feature extraction, the detector combines evidence from every signal family. This ensemble approach reduces dependence on one fragile measurement.
Signals can reinforce or contradict one another. Predictable wording may suggest AI, while varied syntax and personal vocabulary may support human authorship.
The system evaluates the strength, consistency, and distribution of that evidence. It then maps the combined result into calibrated output categories.
Calibration matters because a raw model score is not automatically a meaningful probability. Scores require testing against relevant human, AI, and mixed-text examples.
We update evaluation data as writing models and editing practices change. Performance can decline when new generators produce patterns missing from older test sets.
We do not publish fixed internal weights or exploitable thresholds. Those values can change during calibration and could help deliberate evasion.
Transparency should explain what the system measures and how users should interpret results. It should not provide instructions for defeating safeguards.
Understanding AI, HUMAN, and MIXED Probabilities
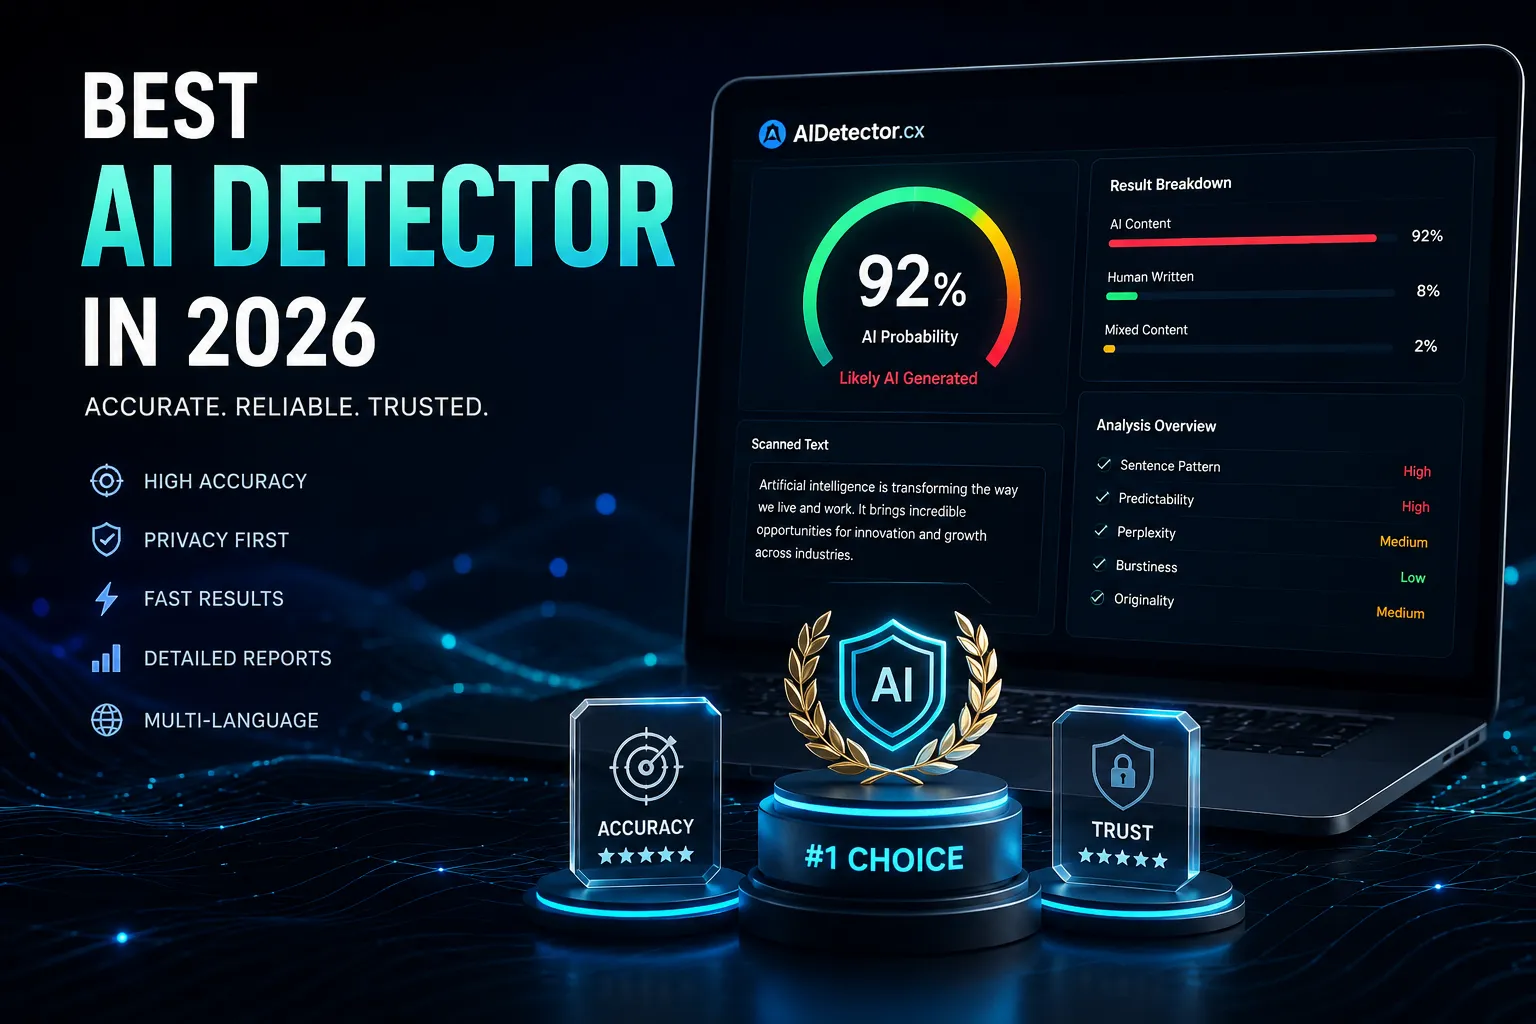
The result displays three probabilities that describe the model’s current interpretation. They represent competing explanations for the submitted passage.
The AI probability estimates how strongly the observed patterns resemble machine-generated writing within the detector’s evaluated conditions.
The HUMAN probability estimates how strongly those patterns resemble human-authored writing. It does not certify identity, originality, or ownership.
The MIXED probability reflects conflicting or blended evidence. This category can appear when human and AI patterns coexist, or when evidence remains structurally ambiguous.
Mixed does not mean the displayed percentage equals an exact amount of AI-written content. The detector estimates categories, not a precise authorship ratio.
The three values provide more information than a binary label. Users can see uncertainty that would disappear behind a simple human-or-AI verdict.
AI Probability Is Not the Same as Confidence
AI probability describes which origin category the evidence supports. Confidence describes how stable and consistent that interpretation appears.
A passage may show the highest probability for AI while retaining moderate confidence. AI is the leading explanation, but uncertainty remains meaningful.
Short text often produces lower confidence because fewer sentences provide less evidence. Conflicting styles, mixed authorship, and heavy editing can also reduce confidence.
High confidence still does not create proof. It means the measured signals agreed strongly under the system’s present calibration and testing conditions.
Users should examine both values together. A headline label without its confidence level can exaggerate what the detector actually knows.
Balanced Detection: The Primary Review Mode
Balanced Detection is designed to reduce false positives while preserving useful sensitivity. It requires stronger combined evidence before favoring an AI interpretation.
This mode is appropriate for education, publishing, recruitment, and professional review. In those settings, a mistaken accusation can cause serious harm.
Balanced Detection gives greater practical weight to uncertainty. Human-like evidence and contradictory signals can prevent weaker AI indicators from dominating the outcome.
It remains capable of missing heavily edited or humanized AI text. That trade-off follows its conservative purpose and should be understood before use.
For most decisions involving people, Balanced Detection should provide the starting result. Supporting evidence should then come from the document’s broader context.
Aggressive Detection: A Higher-Sensitivity Review
Aggressive Detection looks harder for weaker and less obvious AI-like patterns. It is intentionally more sensitive than Balanced Detection.
That sensitivity can help reviewers examine paraphrased, polished, or partially generated material. It also increases the possibility of false positives.
An Aggressive result should function as a review signal, not an accusation. It identifies text deserving closer examination under a more sensitive threshold.
The mode can support internal quality checks, editorial screening, and comparative analysis. It should not independently determine grades, discipline, employment, or publication decisions.
When both modes strongly agree, the interpretation has broader model support. When they disagree, the disagreement itself provides valuable information.
What Disagreement Between Modes Means
Balanced and Aggressive Detection are not competing claims where one must be wrong. They examine the same passage under different sensitivity priorities.
An Aggressive AI result with a Balanced human result usually indicates weaker or borderline AI-like evidence.
The text may also reflect formal or highly edited human writing. Reviewers should treat that pattern as uncertainty.
They can inspect highlighted passages, request drafts, verify citations, or discuss the writing process.
Mode disagreement is especially useful because it exposes threshold sensitivity. A single detector label would hide that important limitation.
Our purpose is not to maximize AI accusations. Our purpose is to provide evidence that remains understandable, cautious, and useful.
Language Detection and Multilingual Calibration
Writing patterns vary across languages. Sentence structure, morphology, punctuation, word order, and vocabulary diversity cannot share one universal English-centered baseline.
The system identifies the likely language before interpreting linguistic signals. Language-aware calibration then adjusts how evidence contributes to the final result.
This process reduces avoidable distortions, but it cannot eliminate every bias. Performance may vary across languages, dialects, domains, and available evaluation data.
Research has documented serious fairness concerns in this field. One Patterns study found frequent misclassification of non-native English writing.
That evidence supports cautious multilingual design and transparent limitations. It also explains why language information should appear beside every detection result.
Beta language support should be interpreted carefully. Users should expect wider uncertainty where testing data remains smaller or less representative.
Why Short Text Is Harder to Classify
Reliable pattern analysis needs enough language to compare several sentences. A short sample offers fewer word choices, structures, transitions, and variation points.
One polished paragraph may resemble careful human writing or routine AI output. The available evidence may not distinguish those explanations reliably.
Very short passages can also magnify one unusual feature. A repeated phrase or rigid sentence structure may disproportionately influence the score.
Users should submit complete, continuous passages whenever possible. Combining unrelated sections creates another distortion and may produce misleading mixed signals.
When confidence remains limited, the responsible conclusion is uncertainty. Adding stronger language to the verdict would not add stronger evidence.
Editing, Paraphrasing, and Translation
Editing changes the signals that detectors measure. A person can restructure generated text, while grammar software can regularize genuinely human writing.
Paraphrasing may replace predictable phrases, change syntax, or redistribute vocabulary. Those changes can weaken evidence without changing the passage’s original production history.
Translation introduces another layer of uncertainty. The translated text reflects the source, translation system, target language, and subsequent human revision.
Humanized AI text is therefore difficult to classify consistently. So are heavily edited essays, collaborative documents, and passages assembled from multiple sources.
Our detector reports the patterns visible in the submitted version. It cannot reconstruct every invisible step that occurred before submission.
What Our Detector Cannot Prove
No AI detector can directly observe who typed a document. It cannot access private drafting history unless a user separately provides that evidence.
It cannot prove misconduct, intent, plagiarism, or policy violations. Those conclusions require context, rules, records, and fair human judgment.
It also cannot guarantee perfect detection across every model, language, subject, or editing method. Generative systems and human writing practices continually change.
OpenAI previously withdrew its public classifier because of low accuracy. That decision illustrates why strong claims require caution.
Detection remains useful when its limits are respected. Problems begin when probabilistic evidence is presented as unquestionable proof.
Responsible Use for Teachers and Institutions
Teachers should begin with the Balanced result, confidence level, and flagged passages. They should then compare those findings with the student’s previous work.
Draft history, notes, citations, source knowledge, and the student’s explanation provide stronger context. None should be replaced by one automated score.
Institutions need written review procedures. Those procedures should define acceptable AI use, required disclosure, human oversight, appeal rights, and evidence standards.
Students should have an opportunity to explain their process. A detector result should begin a careful conversation, not end one.
Non-native English writers and students using accessibility tools deserve particular caution. Formal, predictable, or corrected language must not become automatic evidence of misconduct.
Responsible Use for Writers and Publishers
Writers can use detection results as a quality-control signal. Repetitive, templated, or unsupported passages may need revision regardless of their actual origin.
Editors can compare both modes to identify uncertain sections. They should inspect factual support, citations, originality, voice, and audience value separately.
A high human probability does not confirm factual accuracy. Human writers can make errors, invent sources, or copy material without attribution.
Likewise, a high AI probability does not automatically make content useless. Responsible publishing depends on disclosure, verification, originality, and editorial standards.
The detector supports those decisions by revealing linguistic evidence. It does not replace the professional judgment required to make them.
How to Read Your Result Correctly
First, confirm that the detected language matches the submitted text. An incorrect language classification can weaken the relevance of later interpretation.
Second, review all three probabilities rather than only the largest number. A close distribution indicates more ambiguity than one dominant category.
Third, check confidence. Low or moderate confidence should narrow any conclusion, especially for short, translated, creative, or heavily edited passages.
Fourth, compare Balanced and Aggressive Detection. Agreement strengthens the consistency of the signal, while disagreement highlights sensitivity and uncertainty.
Fifth, examine flagged passages and external context. Look for quotations, templates, technical terminology, editing tools, or collaborative writing.
Finally, avoid converting an estimate into a verdict about a person. The result concerns text patterns, not character, honesty, or intent.
Frequently Asked Questions
Does a 70% AI probability mean 70% of the text was AI-written?
No. It means the detector found stronger support for the AI category under its present model and calibration.
It does not measure an exact percentage of AI-authored sentences. Sentence-level evidence can help locate changes, but authorship boundaries remain estimates.
Why can Balanced and Aggressive Detection show different results?
They use different sensitivity priorities. Balanced Detection emphasizes reducing false positives, while Aggressive Detection gives weaker AI-like evidence more influence.
Their disagreement shows that the passage sits near an interpretive boundary. That outcome calls for contextual review, not an automatic accusation.
Can human writing receive a high AI probability?
Yes. Highly formal, repetitive, predictable, short, translated, or heavily corrected human writing can resemble patterns associated with generated text.
This possibility explains why the platform displays confidence, language, mixed probability, sentence-level information, and two detection modes.
Can AI-written content receive a human result?
Yes. Extensive rewriting, paraphrasing, translation, collaborative editing, or generation from unfamiliar models can reduce detectable AI-like patterns.
No detector can guarantee identification under every condition. Results should support investigation and quality review, not replace them.
Does the detector store or search my text online?
The detector analyzes submitted language for authorship signals. AI detection itself does not require searching the public web for matching sources.
Users should consult the current privacy policy for exact storage, retention, and account-processing terms. These operational terms can change independently of detection methods.
A Transparent Result Is More Useful Than a Certain-Sounding One
AI detection is a probabilistic classification task, not a digital fingerprint test. Honest systems must communicate uncertainty instead of hiding it.
AIDetector.cx combines multiple linguistic signals, sentence-level analysis, language-aware calibration, three probability categories, confidence reporting, and two complementary detection modes.
Balanced Detection provides the safer starting point for decisions involving people. Aggressive Detection offers a more sensitive second view for deeper examination.
Together, they reveal both evidence and uncertainty. That transparency helps users investigate writing responsibly without mistaking a statistical estimate for proof.
The final decision should always include human review, relevant context, and fair procedures. Detection can inform judgment, but it should never replace judgment.
Recommended Tools
Stay ahead of AI detection trends
Get the latest guides, research, and product updates from AIDetector.cx delivered to your inbox.